🔍 Read the full analysis: From Numbers To Models: AI’s Experiment With Weight-Space Programming on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Four MIT CSAIL researchers report that OpenAI’s GPT-6 Astra identified, repaired and wrote small neural networks by working directly with their weights. Their November 2 blog post records successful tests, but also failures; the work is not peer-reviewed, and the reported experiments are limited in scale.
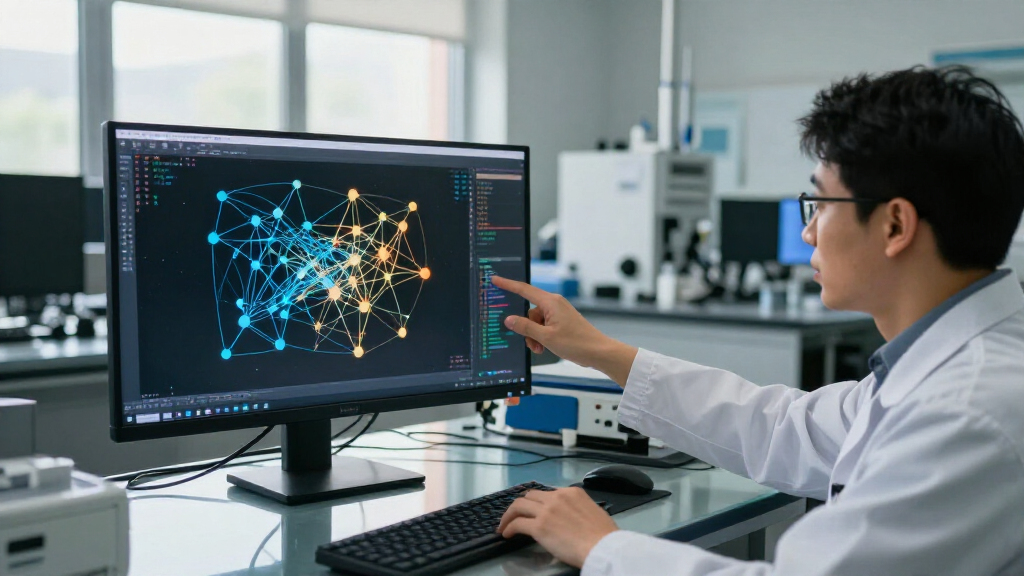
Four researchers at MIT’s Computer Science and Artificial Intelligence Laboratory say they tested whether OpenAI’s GPT-6 Astra could interpret and change neural-network weights directly, rather than relying on a training algorithm. In a November 2 blog post, they describe experiments in which the model identified small networks’ functions, repaired two failing systems and generated new networks, while also recording tests where its edits did not help.
The researchers call the method weight-space programming: a language model reasons about the numbers, or weights, that determine how another neural network behaves. According to their post and released logs, the experiments did not use gradient descent to make the changes. The team says Astra had no shell, web search or file-editing tools; in some tests it received weights as text and responded directly, while other tests ran code it wrote in a sandbox.
Among the reported results, Astra named the games represented by four of four small game-playing networks and identified the shape generated by three small image models. It also changed 3.5% of a car-control network’s weights: the authors report that it went from no successful reverse manoeuvres in 256 episodes to success in 1,024 of 1,024 episodes after the edit.
In a separate test, an edit affecting 0.016% of Qwen3.5-0.8B’s weights coincided with an increase in its MATH-500 score from 7.9% to 48.1%, according to the researchers. Astra also generated a 9-by-9 Go network from zero weights; the post says it beat a same-size comparison network trained on about 20.5 million games in 50 test runs. These are the team’s reported results, not evidence that the approach works broadly across models or tasks.
Infographic 01 · Eight experiments
Read, fix, write: what GPT-6 Astra did with raw weights
Every experiment in the weight-space programming post, with the size of the network, the result and how it went.
Read
- 1Which game was this network trained on?4 reinforcement-learning policies · 17,253 weights each · weights as text, no toolsRight game for 4 of 4, without a list of options✓ Worked
- 2What does this image model draw?3 tiny diffusion models · 23,824 weights · no forward pass allowedRight shape for 3 of 3, but drawn as outlines; the models draw filled shapes✓ Worked
- 3Which language did this model learn?3 character-level transformers · 7.16M weights · middle blocks only, never runRight language 3 of 3; every copying head found, none invented✓ Worked
- 7Which of two models is sycophantic?3 pairs of Gemma 3 270M fine-tunesWeights alone: could not tell in 4 attempts. With attention patterns: 3 of 3! Partly
Fix
- 4Repair a car that never backs upKinetix control network · 171,664 weights · one reply, no tools0 of 256 episodes before, 1,024 of 1,024 after; 3.5% of weights changed✓ Worked
- 8Make Qwen3.5-0.8B better at maths0.8 billion weights · Python over the weights · 10 / 25 / 50 test passesMATH-500 7.9% to 48.1% with 50 passes (12.3% and 14.1% with 10 and 25)! Partly
- 8bSame task, a model that does not loopGemma 3 270M · 5 to 50 test passesMATH-500 6.8% to at most 7.7%: “not established”✕ Failed
Write from zero
- 5Write arcade-game networks3 MinAtar games · 20,486 weights, all starting at 0 · one reply, no toolsBeat the 100M-step comparison networks in 3 of 3, the 500M-step ones only in Breakout! Partly
- 6Write a 9×9 Go network1,480,274 weights, all starting at 0 · no training, no search0 passes: 54% vs small trained nets. 50 passes: 70–79% vs same-size nets trained on ~20.5M games✓ Worked
✓ Worked · ! Partly or with conditions · ✕ Failed. One run per setting, no error bars. A blog post with complete logs, not a peer-reviewed paper.
Sources: Takehi, Teoh, Zhang, Khattab (MIT CSAIL), blog post, 2 Nov 2026, lm_understand-logs (CC BY 4.0). Model: OpenAI GPT-6 Astra via the Codex CLI, built-in tools switched off.
Powered by Thorsten Meyer AI
Direct Edits Could Change Model Maintenance
If the results hold up under independent testing, weight-space programming could offer a different way to inspect or make targeted changes to small models. Instead of gathering additional training data and running a lengthy optimization process, developers might ask a language model to locate a particular behavior in a network and alter a limited set of weights. The reported Qwen result, in particular, suggests a possible route to testing narrow fixes without changing the entire model.
That prospect remains hypothetical for practical deployment. The experiments do not establish that direct edits are reliable, safe or economical for large commercial systems. A change that improves one benchmark may affect other behaviors, and the source material does not establish how well these edits generalize beyond the tested models. For organizations, the work also draws attention to model provenance: direct access to weights could be useful for auditing, but makes it important to know which weights are being inspected and modified. No immediate change for users is reported.
Products Worth Considering

DJI Osmo Mobile 8 Smartphone Gimbal with Mic Mini Transmitter, Infinity Black

Amazon Kindle Paperwhite (2024), 16 GB, 7-inch Display, Black

LG UltraGear 34GX90SA-W 34-inch WQHD Curved OLED Gaming Monitor
As an affiliate, we earn on qualifying purchases.
A Different Route to Neural-Network Changes
Neural-network weights are numerical values that influence how a model processes inputs and produces outputs. In conventional training, an optimizer adjusts those values repeatedly against data and an objective. The MIT researchers instead asked a general-purpose language model to infer what the weights represented and, in selected tests, to propose edits.
The approach builds on the idea that neural networks can be understood as software encoded in weights. In 2017, Andrej Karpathy described this as “Software 2.0,” arguing that optimization writes programs into neural-network weights. The new work tests whether a language model can reason about those values directly, rather than leaving their adjustment entirely to an optimizer.
The source describes the release as a research blog post with public logs, not a peer-reviewed paper, and says it was not posted on arXiv. The experiments came from one research group and used small networks, with one run per setting reported in the source. A Hugging Face engineer reportedly reconstructed the edited Qwen model from the logs and obtained a 51.0% MATH-500 score, an additional check that is not a substitute for a controlled, independent study.
““not through an optimizer, and in particular not with gradient descent””
— MIT CSAIL researchers, in their November 2 blog post
How Far the Results Extend
The evidence remains limited to the experiments described by this one research group. The source reports one run per setting, small networks and a narrow set of tasks; it does not establish whether the results replicate across model families, larger networks or different evaluation conditions. The blog post is not peer-reviewed, although logs are public and one outside engineer reportedly reproduced the edited Qwen result.
The team also reports clear failures. Astra could not distinguish an honest model from a sycophantic one using weights alone, and edits to Gemma 3 270M did not improve its maths score. The researchers say editing could not supply an ability the model did not already have. It is also not clear from the source whether improvements on the reported tests came with trade-offs on other tasks, or how much expert review would be needed before edited weights could be trusted.
Independent Tests Are the Next Step
The immediate next step is scrutiny of the released logs and replication of the experiments by other researchers. Broader tests would need to check whether the edits persist across repeated runs, model families and evaluations beyond the tasks used in the post. For repairs, testing should also look for regressions in behaviors that were not the target of an edit.
The source does not announce a peer-reviewed paper, a product release or a deployment schedule. Until such evidence or plans emerge, weight-space programming is best understood as an early research direction, not a replacement for current model training or a tool that users can apply today.
Key Questions
What is weight-space programming?
It is the approach described by the MIT researchers in which a language model reads or changes another neural network’s weights directly, rather than relying on gradient descent to adjust them.
What did GPT-6 Astra reportedly do?
The researchers say Astra identified the functions of small networks, edited a car-control network and a language model, and generated small game-playing networks, including a 9-by-9 Go network.
Does the work show that AI can reliably repair models?
No. The post reports successful cases as well as failures, including edits that did not improve Gemma 3 270M’s maths score. The reported experiments are limited and have not been described as peer-reviewed.
Can users use this method now?
The source reports no product or public tool for users. It presents the work as an early research result, with broader replication and evaluation still needed.
Source: ThorstenMeyerAI.com