📊 Full opportunity report: What Accountants Should Know About AI-Coded Book Reviews on IdeaNavigator AI — validation score, market gap, and execution plan.

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
IdeaNavigator AI proposes a risk-flag review queue for accounting firms using AI transaction categorization, surfacing suspicious entries instead of requiring staff to recheck every transaction. The proposal is an unvalidated product concept: testing it on three firms’ prior-quarter ledgers is suggested, but no results, customer adoption or measured time savings are reported.
IdeaNavigator AI has proposed a risk-flag review queue for accounting firms that use AI to categorize bookkeeping transactions, aiming to direct staff toward suspicious entries rather than rechecking every line. The concept is a product opportunity, not a reported launch or validated result; its suggested first test would compare flags with confirmed errors in three firms’ prior-quarter ledgers.
The proposal addresses a specific control problem: automated bookkeeping can produce entries that look complete while carrying the wrong category. Examples include a subscription coded as fuel or an owner draw recorded as an expense. If staff must inspect every automated entry to catch those mistakes, the review work could erode the time savings that categorization tools are meant to provide.
The proposed minimum viable product would connect to QuickBooks or Xero and score incoming transactions for risk signals. These could include unusual vendor-category combinations, differences between transaction amounts and supporting documents, and owner spending that appears personal. The queue would show only the suspected 10% of transactions, alongside the relevant source document and a plain-language explanation of the flag.
That 10% is a design target in the proposal, not a measured result. IdeaNavigator AI recommends running the scoring system retrospectively on three firms’ last-quarter ledgers, then counting confirmed miscodings caught and flags raised. It describes a promising signal as catching most known errors while flagging less than 15% of transaction volume. No trial findings, error-detection rate, pricing figures or customer commitments are provided.
AI-coded book reviews A proposal awaiting proof
IdeaNavigator AI proposes a risk-flag queue to focus accountants on suspicious entries. The concept has no reported trial results or customer adoption.
What the queue would flag
Risk signals would direct human attention; a flag would not confirm an error.
Unusual categories
A subscription coded as fuel could be sent for review.
Amount mismatches
Differences from supporting documents could raise a flag.
Personal-looking charges
Owner spending that appears personal could be prioritized.
How firms could test it
The proposal suggests a retrospective check using prior-quarter ledgers.
Apply it to ledgers from three firms.
Compare flags with independently confirmed miscodings.
Record the share flagged and reviewer time required.
Promise and proof
The business case depends on useful detection and manageable review effort.
- Focus staff on suspicious entries
- Keep routine transactions in the automated workflow
- No reported accuracy or time savings
- No pricing, customer commitments or trial findings
A Targeted Check on Automated Entries
For bookkeeping and client accounting services firms, the potential benefit is a more focused review process: staff could spend attention on entries that show warning signs, while routine transactions remain in the automated workflow. The proposed measure is not simply how many entries are flagged. Firms would need to know whether the system finds genuine errors and how much extra review its flags create.
The stakes are practical as well as operational. Misclassified transactions can affect the books used for management reporting, tax preparation and other accounting work. A risk score would not itself confirm an error or replace professional judgment; it would be a way to prioritize human examination. Firms would need evidence that the queue catches meaningful mistakes without overwhelming reviewers with false alarms.
The commercial model in the proposal is monthly pricing per client ledger, sold to firms and justified by review hours saved. That makes validation central to the business case: without measured reductions in review time and evidence of useful error detection, firms cannot readily compare the cost with the value.
Products Worth Considering

Logitech MX Keys S Combo Wireless Keyboard and Mouse, Graphite
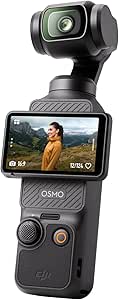
DJI Osmo Pocket 3 Vlogging Camera with 1-Inch CMOS Sensor and 4K/120fps Video

Bose Lifestyle Ultra Soundbar and Ultra Subwoofer Bundle
As an affiliate, we earn on qualifying purchases.
The Review Gap in AI Bookkeeping
The proposal is framed around accounting firms adopting AI categorization tools during 2025–2026. It argues that faster categorization does not remove the risk of incorrect coding, leaving firms with a choice between checking all transactions or accepting entries that may be wrong. The material offers that as the product rationale, but does not provide adoption statistics or independent evidence quantifying the size of the problem.
Its suggested starting point is deliberately narrow: accounting-firm partners or operations leads already running AI categorization, rather than every business that keeps digital books. The review layer would sit alongside existing accounting software and use ledger data and supporting documents to prioritize checks. The proposal does not describe a replacement for QuickBooks, Xero or an accountant’s final review.
Detection Rates and False Alarms
No working product or test results are reported. It is unknown how accurately a proposed scorer could distinguish genuine miscoding from unusual but correct transactions, or whether its risk signals would perform consistently across firms, industries and transaction types. The suggestion to flag the suspicious 10% is a product design aim, while the under-15% figure is a proposed validation benchmark; neither is established performance data.
Other open questions include how the system would access and protect financial records and source documents, how it would handle incomplete documentation, and whether its explanations would give reviewers enough information to act. The proposal also does not state how review outcomes would feed back into the scoring system, what the service would cost, or how firms would calculate time saved. Those details would shape both operational suitability and the product’s commercial case.
A Three-Firm Ledger Test
The next step described is a retrospective test using the previous quarter’s ledgers from three firms. A useful evaluation would compare the queue’s flags with independently confirmed errors, report the share of total transactions sent for review, and record how much reviewer time the process takes. The proposal’s stated target is to catch most known errors while keeping flags below 15% of volume.
Until such results are available, the concept should be treated as an untested workflow rather than a proven safeguard or source of savings. No deployment, product release, firm participation or timetable for testing has been announced in the material provided. The key evidence to watch for is whether the approach detects meaningful errors at a manageable review rate—and whether the time it saves exceeds the effort needed to investigate its alerts.
Source: IdeaNavigator AI
Key Questions
Has the AI-coded bookkeeping review tool launched?
No launch is reported. The material describes a proposed product and a suggested way to test it, not a released service.
What transactions would the proposed queue flag?
It would look for signals such as unusual vendor-category matches, differences between transaction amounts and supporting documents, and owner spending that appears personal. A flag would prompt human review; it would not by itself establish that a transaction was misclassified.
How would the proposal be tested?
IdeaNavigator AI suggests applying the scorer to three firms’ prior-quarter ledgers and comparing confirmed errors caught with the number of transactions flagged. Its proposed benchmark is catching most known errors while flagging less than 15% of volume.
What evidence is still missing?
There are no reported trial results, measured accuracy rates, time savings, pricing details or customer commitments. It is also unclear how the system would handle false alarms, document gaps and the protection of accounting records.
Source: IdeaNavigator AI