TL;DR

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The AI content industry predominantly licenses high-profile, brand-name corpora, leaving smaller data sources underserved. This trend influences market dynamics, licensing practices, and the diversity of training data.
The AI content market is increasingly paying premium prices for datasets associated with well-known brands, effectively sidelining smaller, less prominent data sources. This trend impacts the diversity of training data and raises questions about market fairness and data access.
Industry insiders and analysts indicate that licensing agreements for large, brand-name corpora dominate the AI content market. These datasets, often curated by major technology firms or prominent publishers, command higher prices due to their perceived quality and relevance.
According to Thorsten Meyer AI, this focus on high-profile corpora is driven by the demand for high-quality, reliable datasets that can improve model performance. Smaller or niche data sources, often referred to as the ‘long tail,’ struggle to secure licensing deals or are priced out of the market, leading to reduced diversity in training data.
This trend has significant implications for the AI ecosystem, including potential biases in models trained on a limited range of data sources and reduced opportunities for smaller data providers to participate economically.
Why It Matters
This development matters because it influences the fairness and diversity of AI training data, potentially leading to biased or less representative AI models. It also impacts the data economy, where smaller providers may be marginalized, reducing competition and innovation in data sourcing.
Products Worth Considering

Bose QuietComfort Headphones (2nd Gen), Wireless Noise-Cancelling Over-Ear Headphones, Black
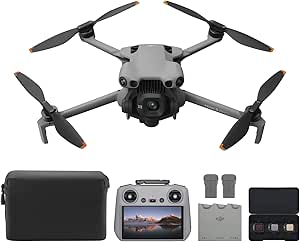
DJI Mini 5 Pro Fly More Combo Plus with DJI RC 2

Samsung 27 Odyssey OLED G5 (G50SF) QHD QD-OLED Gaming Monitor
As an affiliate, we earn on qualifying purchases.
Background
Historically, AI models have been trained on diverse datasets, including publicly available, open-source, and proprietary sources. Recently, however, there has been a shift towards licensing high-profile corpora, often associated with major brands, which are viewed as more reliable and valuable. This shift is partly driven by the increasing commercial value of AI models and the desire for high-quality training data.
Previous industry patterns showed a broader inclusion of varied sources, but market dynamics now favor large-scale licensing agreements with well-known entities, which can command higher prices and influence data access policies.
“The AI content market is increasingly favoring licensing large, brand-name corpora, leaving the long tail of smaller data sources marginalized.”
— Thorsten Meyer AI
“High-profile datasets are seen as more reliable, which is why companies are willing to pay a premium, often at the expense of smaller providers.”
— Industry analyst
What Remains Unclear
It remains unclear how long this trend will persist or whether new policies or market shifts will enable smaller data sources to regain prominence. The impact on model bias and diversity is also still being studied.
What’s Next
Industry stakeholders are expected to explore alternative licensing models and data-sharing initiatives to broaden access. Further research will assess how these trends influence AI model fairness and data economy dynamics.
Key Questions
Why does the AI market prefer brand-name corpora?
Because they are perceived as more reliable, higher quality, and more relevant, which can improve model performance and justify higher licensing costs.
What is the ‘long tail’ in AI data sourcing?
It refers to smaller, less prominent data sources that are often overlooked or priced out of licensing agreements, despite their potential value for diversity and fairness.
How does this focus on big datasets affect AI fairness?
It can lead to biased models that reflect the data of dominant sources, reducing diversity and potentially perpetuating systemic biases.
Are there efforts to include more diverse data sources?
Yes, some initiatives aim to democratize data access and develop alternative licensing models, but widespread change has yet to occur.
Source: Thorsten Meyer AI